Architecting for Resilience in Modern Software
Design principles that ensure your distributed systems remain available, self-healing, and performant under unpredictable load conditions.
Key Takeaways
- Distributed resilience patterns: Circuit Breakers, Bulkheads, and service-level fault isolation.
- Clean Architecture (Hexagonal) to decouple core domain logic from infrastructure changes.
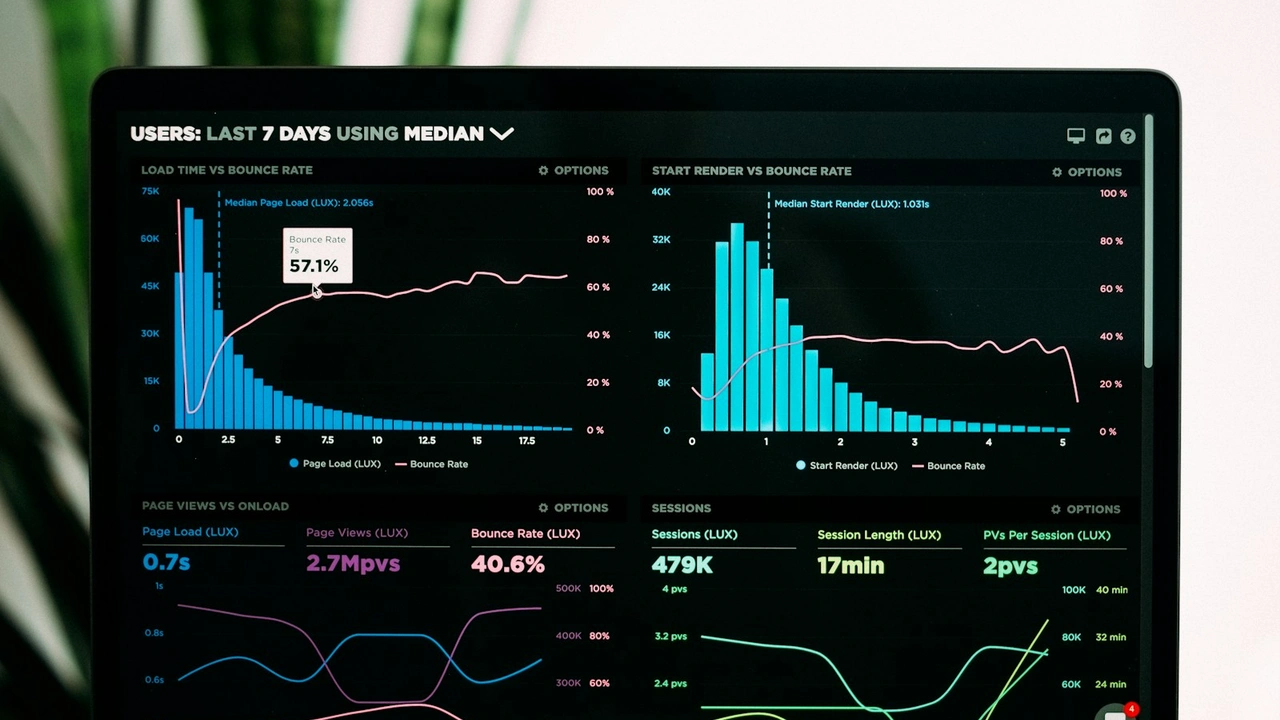
- Comprehensive 3D observability combining RED metrics, centralized JSON logs, and Jaeger tracing.
- Proactive Chaos Engineering in production to validate self-healing capabilities before incidents occur.
In modern distributed systems, component failure is not a remote possibility or an extraordinary event: it is a statistical certainty that occurs with predictable frequency. Networks experience variable latency and packet loss. Third-party services suffer outages and degradations without warning. Databases experience contention spikes under load. SSL certificates expire. Containers restart. In a system with one hundred microservices, if each carries a 99.9% availability SLA, the composite system availability is approximately 90%. Without explicit resilience design, partial failures cascade into total failures.
Resilience is not a feature added at the end of a project; it is a design discipline that permeates every architectural decision from day one. The foundation of a truly resilient system is strict separation of concerns through Clean Architecture — also known as Hexagonal Architecture or Ports and Adapters — which isolates core business rules (the immutable domain nucleus) from all infrastructure dependencies (databases, external APIs, messaging systems, web frameworks). When a database provider changes or an external API goes down, only the external adapter is replaced; the business logic remains completely intact and unmodified.
Built upon this architectural foundation, we implement a comprehensive battery of production-proven fault tolerance patterns: Circuit Breakers to automatically interrupt requests to failing services (preventing accumulated latency from collapsing thread pools), Bulkheads to isolate execution thread groups per service (ensuring one integration's failure doesn't affect others), Throttling and Rate Limiting to protect downstream services from sudden load spikes, and the Outbox Pattern to guarantee eventual consistency in asynchronous event architectures without resorting to fragile distributed transactions.
Resilience validation is performed proactively, not reactively. We deploy full three-dimensional observability with OpenTelemetry: RED metrics (Rate, Errors, Duration) per service in Prometheus/Grafana, centralized structured logs in Loki or Elasticsearch, and end-to-end distributed traces in Jaeger or Tempo that let engineers visualize exactly the journey of every request across all microservices. And we go further: we practice Chaos Engineering systematically, injecting controlled failures in production (artificial latency, pod terminations, network partitions) to verify the system behaves exactly as designed when something goes wrong.
The Challenge of Distributed Complexity
In distributed systems at enterprise scale, individual component failure is completely inevitable — it's simply a matter of when, not if. Networks experience variable latency and packet loss. Third-party services (payment providers, geolocation APIs, identity services) suffer degradations without warning. Resilience is not reacting to incidents when they happen, but designing software from the ground up to tolerate partial failures gracefully, without a degraded component triggering the cascading collapse of the entire system. A truly resilient system fails silently in parts, not noisily in its entirety.
Clean Architecture & Dependency Inversion
Clean Architecture — also called Hexagonal Architecture or Ports and Adapters — is the foundation on which we build resilient systems. The core principle is Dependency Inversion: the domain nucleus (business rules) does not depend on any framework, database, or external service. External adapters depend on the domain, not the other way around. This means a database provider failure, an ORM swap, or a messaging broker replacement is completely contained within the corresponding adapter, without touching or risking the central business logic. Systems built on this principle are inherently easier to test, modify, and maintain over time.
Fault Tolerance & Isolation Patterns
We deploy a comprehensive arsenal of production-proven resilience patterns. Circuit Breakers (implemented with Resilience4j or Polly) detect degraded services and automatically open the circuit, returning fallback responses without blocking thread pools. Bulkheads isolate thread groups per external service, guaranteeing that connection pool exhaustion with one provider doesn't affect the others. Adaptive Rate Limiting and Throttling protect downstream services from unforeseen load spikes. The Outbox Pattern guarantees eventual consistency in asynchronous events: instead of publishing directly to the message broker (risking message loss if the broker fails), the event is written atomically to the transactional database and a reliable Outbox process publishes it asynchronously.
Three-Dimensional Observability & Chaos Engineering
Observability is the nervous system of resilience. We deploy full three-dimensional telemetry with OpenTelemetry: RED metrics (Rate, Errors, Duration) per service in Prometheus with Grafana dashboards, centralized JSON structured logs with automatic trace ID correlation, and end-to-end distributed traces in Jaeger showing the complete visual journey of each request across all services. On this observability foundation, we practice Chaos Engineering systematically with tools like Chaos Monkey, Chaos Mesh, or Gremlin: injecting artificial latency into inter-service calls, terminating pods randomly during low-demand hours, and simulating network partitions. If the system doesn't survive these experiments in staging, it doesn't reach production.
Resilience as a Core Business Investment
The real cost of not designing resilience from day one is measured in minutes of downtime multiplied by the revenue cost per minute of unavailability. For an e-commerce platform with $100,000 USD daily revenue, a two-hour incident on Black Friday represents $8,300 USD in direct lost revenue, plus immeasurable brand damage. Designing resilience from day one — Circuit Breakers, Bulkheads, Chaos Engineering — is the architectural investment with the highest proven return. Truly resilient software guarantees complete operational continuity during massive traffic spikes, external provider failures, and unforeseen infrastructure events, protecting both revenue and customer trust.
Want to apply this in your organization?
Talk to a Nubework architect.